IMPORTXML in Google Sheets: syntax, XPath examples and errors
IMPORTXML fetches a public web page or XML file and returns the parts that match an XPath query: a heading, a meta tag, all links, the cells of a table. This guide covers the syntax, an XPath cheat sheet, step-by-step examples, how often the data refreshes, what the function cannot read, and the error messages it returns.
IMPORTXML fetches a web page or an XML file and returns the parts of it that match an XPath query:
=IMPORTXML("https://en.wikipedia.org/wiki/Albert_Einstein", "//span[@class='bday']")
The formula loads the Wikipedia page and returns the content of the span element with the class “bday”, the date of birth: 1879-03-14.
IMPORTXML syntax
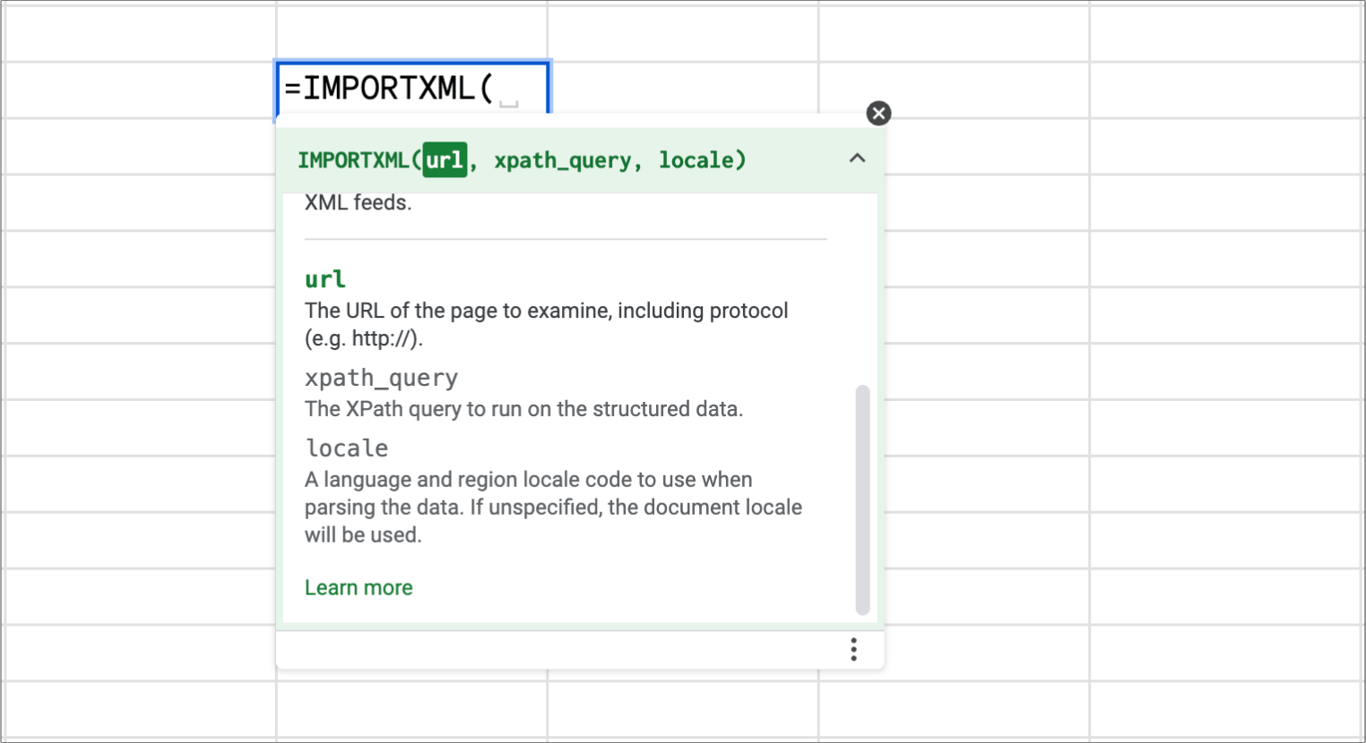
=IMPORTXML(url, xpath_query, [locale])
- url: the address of the page, with its protocol (https://). In quotation marks, or a reference to a cell that holds it.
- xpath_query: the XPath expression that selects what to return.
- locale: optional. A language and region code, such as “en_US”, used to read numbers and dates in the page. Without it, the locale of the spreadsheet applies.
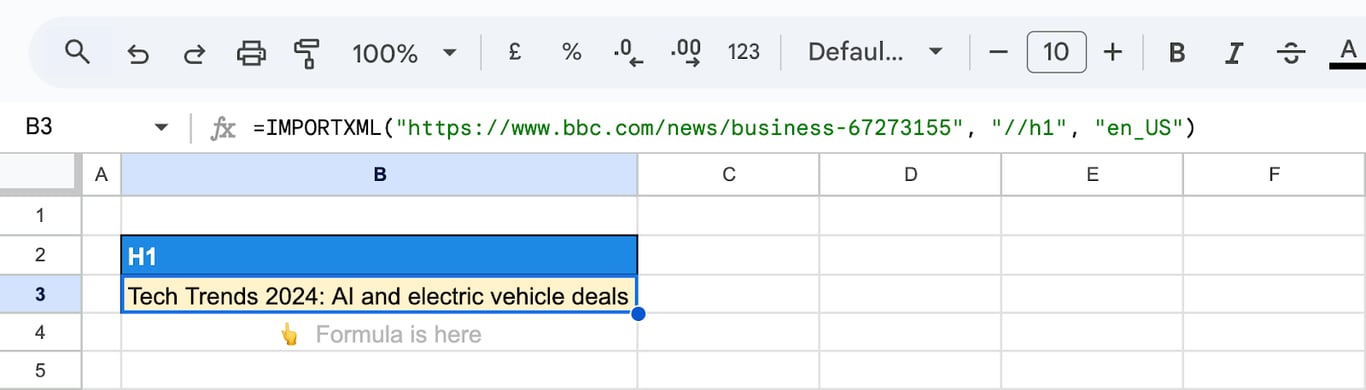
According to Google’s help, the function reads XML, HTML, CSV, TSV and RSS or Atom feeds. Each element that matches the query becomes one row of the result, and an element with several children, such as a table row, spreads across columns.
=IMPORTXML("https://www.bbc.com/news/business-67273155", "//h1", "en_US")
Both arguments can come from cells, which turns a list of URLs into a table: with the address in A2 and the query in B2, =IMPORTXML(A2, B2).
The first time: allow access
The first time IMPORTXML, IMPORTHTML, IMPORTDATA or IMPORTFEED is used in a file, Sheets shows a warning bar above the grid, “Some formulas are trying to send and receive data from external parties”, and the formula shows #REF! until Allow access is clicked in that bar. We saw exactly this in our test file.
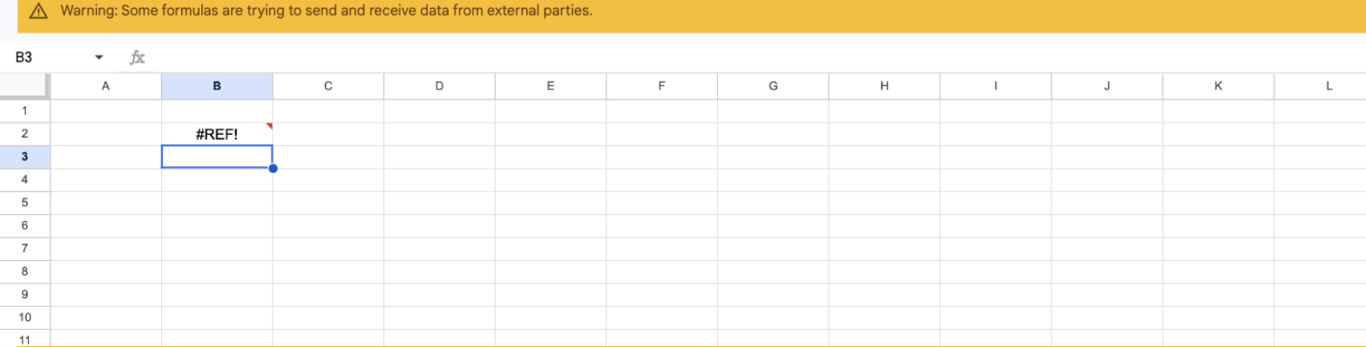
According to Google’s help, the bar appears once per spreadsheet, only an editor of the file can click it, and on a phone it has to be done in a desktop browser.
XPath cheat sheet
XPath describes a path to elements of a page. // means “anywhere in the document”, @ an attribute, and square brackets a condition.
| To get | XPath |
|---|---|
| The page title | //title |
| The meta description | //meta[@name='description']/@content |
| The canonical URL | //link[@rel='canonical']/@href |
| The main heading | //h1 |
| All second-level headings | //h2 |
| All links on the page | //a/@href |
| The text of all links | //a |
| All image addresses | //img/@src |
| An element with an id | //*[@id='price'] |
| Elements with a class | //div[@class='product-name'] |
| A class that contains a word | //span[contains(@class, 'price')] |
| Links to a domain | //a[contains(@href, 'example.com')]/@href |
| The items of lists | //ul/li |
| The rows of tables | //table//tr |
| Only the first match | (//h2)[1] |
Inside the formula the query is wrapped in double quotes, so the values inside it use single quotes: "//span[@class='bday']".
OWOX Data Marts
See your first report built in real time. 15 minutes.
- Connect your data warehouse
- Pick your metrics
- Get a live Google Sheets report
In the time it takes to write a ticket. Then imagine never writing that ticket again.
Book a DemoWe'll use your actual use case
Find the XPath of an element
The example takes the date of birth from the Wikipedia article on Albert Einstein.
-
Open the page, right-click the value you need and choose Inspect. The browser’s developer tools open on that element.
-
Look for something that identifies the element: an id, a class, or its place inside a parent. Here the date sits in a span with the class “bday”, in the machine-readable form 1879-03-14. The span is hidden on the page itself, which is a reminder that the query works on the HTML, not on what you see. A plain
//spanwould return every span on the page, so the class goes into the query. -
Write the query and the formula:
=IMPORTXML("https://en.wikipedia.org/wiki/Albert_Einstein", "//span[@class='bday']")
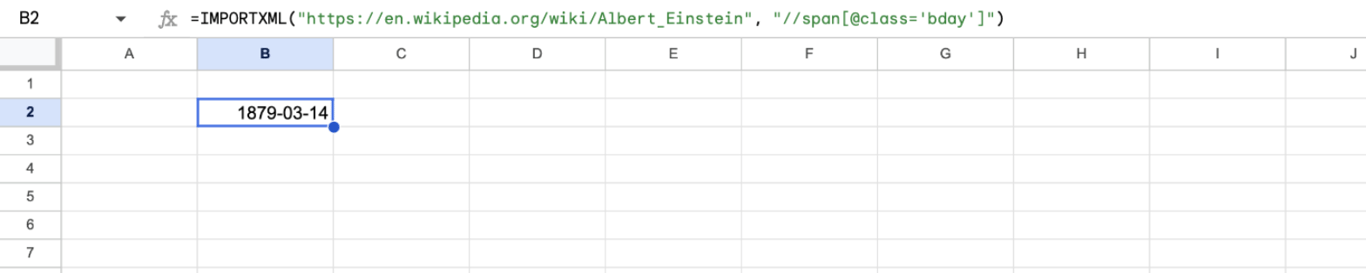
Pages change. This guide first used another article for the example, and its span disappeared when the page was edited: the formula then returned #N/A with “Imported content is empty”. Check an example on the live page before building on it.
The developer tools can also copy a path for you (right-click the element, Copy > Copy XPath), but the generated path is usually long and tied to the exact layout. A short query on an id or a class survives small changes of the page better.
More examples
Attributes: links that point to a domain
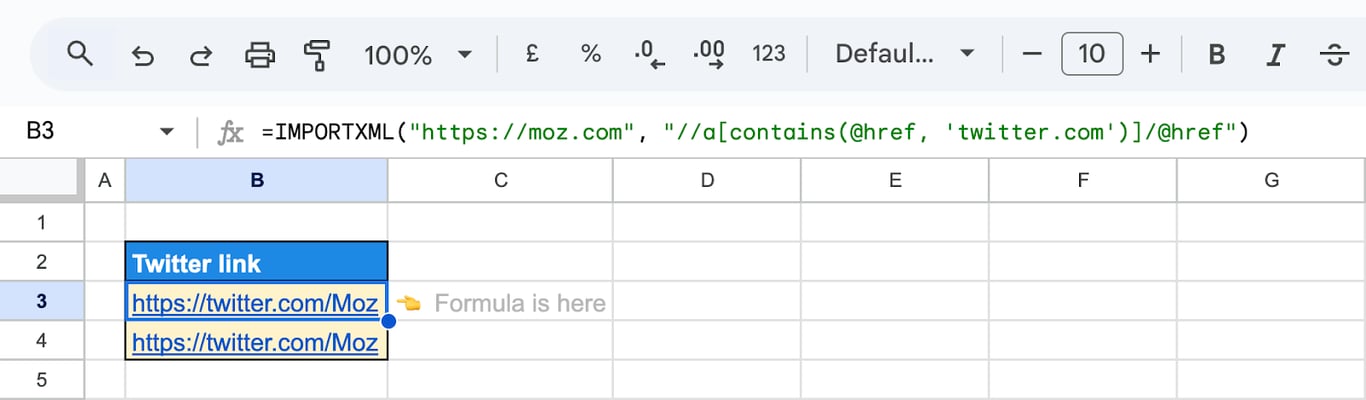
@href returns the address of a link instead of its text, and contains filters by a part of it:
=IMPORTXML("https://moz.com", "//a[contains(@href, 'twitter.com')]/@href")
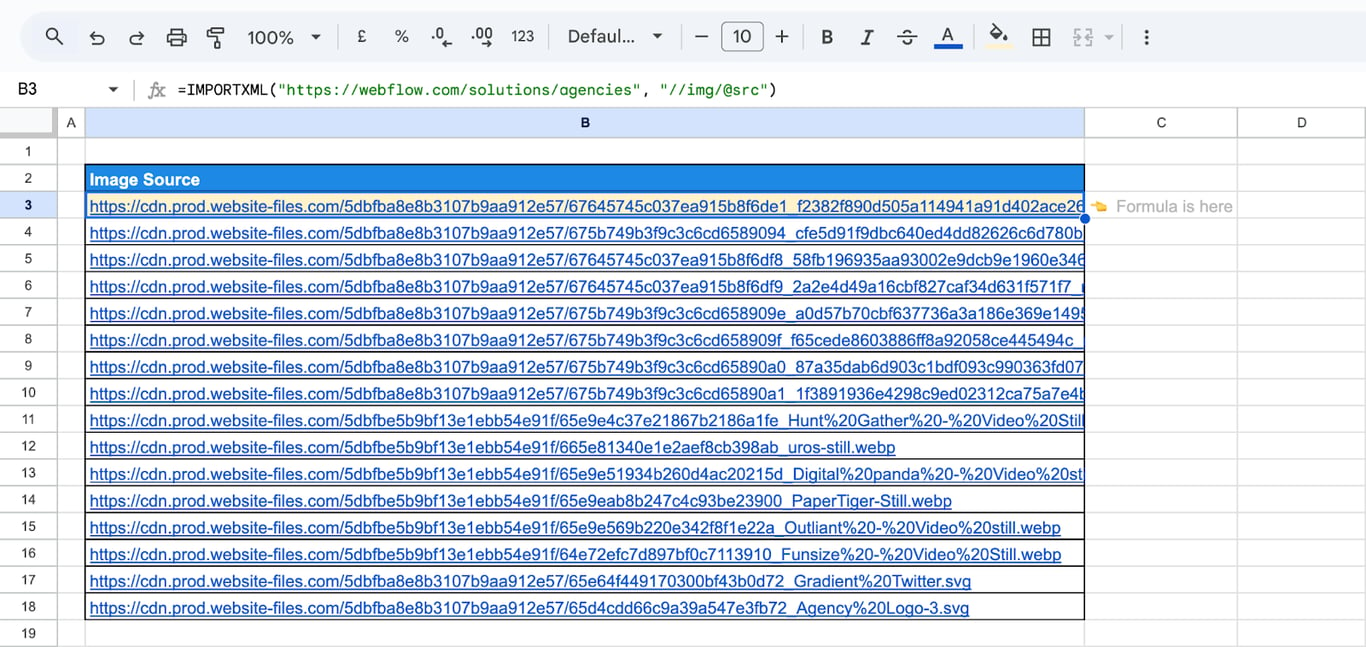
All images of a page
=IMPORTXML("https://webflow.com/solutions/agencies", "//img/@src")
On-page SEO fields for a list of URLs
With page addresses in column A, three formulas give the title, the description and the main heading of each:
=IMPORTXML(A2, "//title")
=IMPORTXML(A2, "//meta[@name='description']/@content")
=IMPORTXML(A2, "//h1")
A query can return several values where one is expected, for example a page with two h1 elements. =INDEX(IMPORTXML(A2, "//h1"), 1) keeps the first.
How often the data refreshes
IMPORTXML re-reads the page by itself. Google’s help says that IMPORTDATA, IMPORTHTML and IMPORTXML check for updates every hour while the spreadsheet is open. Reloading the page does not trigger a refresh; deleting the formula and entering it again does.
What IMPORTXML cannot do
- Pages behind a login. The request comes from Google’s servers, not from your browser, so only public pages can be read.
- Content added by JavaScript. The function reads the HTML the server sends. Prices, tables and lists that a script fills in after the page loads are not there, and the query returns nothing.
- Sites that refuse automated requests. Some sites block them or answer with a different page; the result is an error or content you did not expect.
- A stable result on a changing site. A redesign changes classes and structure, and the query stops matching. Formulas that scrape a page need checking from time to time.
- Large volumes. Import requests are throttled, and Google counts them per creator of the file across all their open files. For hundreds of pages, a dedicated crawler is the right tool.
Check the terms of the site before collecting its content this way.
The other import functions
| Function | Imports |
|---|---|
| IMPORTXML | Any elements of a page or XML file, chosen by XPath |
| IMPORTHTML | A table or a list from a page, by its number |
| IMPORTDATA | A CSV or TSV file from a URL |
| IMPORTFEED | An RSS or Atom feed |
| IMPORTRANGE | A range from another Google spreadsheet |
For a table on a page, start with IMPORTHTML: it needs no XPath.
Errors in IMPORTXML
⚠️ Error: #REF! right after entering the formula, with a warning bar above the sheet.
✅ Solution: The file has not been allowed to fetch external data yet. Allow access in the warning bar.
⚠️ Error: #N/A with “Could not fetch url”.
✅ Solution: The address is wrong or lacks https:// (in our test, “www.owox.com” without the protocol returned this error), the page needs a login, or the site refuses the request. Open the URL in a private browser window to see what an anonymous visitor gets.
⚠️ Error: #N/A with “Imported content is empty”.
✅ Solution: The page loaded, but nothing matches the query. Check the query against the page source (View page source, not the Inspect panel, which shows the page after scripts have run). If the element is not in the source, it is added by JavaScript and cannot be imported.
⚠️ Error: #N/A with “Imported Xml content can not be parsed”.
✅ Solution: The XPath query is not valid: in our test a query with an unclosed bracket returned this message. A bracket or a quote is missing, or curly quotes were pasted. Use straight double quotes around the query and single quotes inside it.
⚠️ Error: #REF! with “Array result was not expanded”.
✅ Solution: The result needs more cells than are free. Clear the cells below and to the right.
⚠️ Error: “Loading…” with the note “Loading data may take a while because of the large number of requests”.
✅ Solution: Too many import requests. Google counts them per creator of the file, across all the files that person has open, so the fix is fewer import formulas, not a faster connection. Replace finished results with values.
⚠️ Error: #ERROR! with “This function is not allowed to reference a cell with NOW(), RAND(), RANDARRAY(), or RANDBETWEEN()”.
✅ Solution: An import function cannot depend on a volatile function, directly or through another cell, which rules out the trick of adding NOW() to the address to force a refresh. TODAY is the one exception.
⚠️ Error: “Result too large”.
✅ Solution: The query returns too much. Narrow the XPath so that it matches fewer elements.
Related guides
- IMPORTHTML: Tables and lists from a page.
- IMPORTDATA: CSV and TSV files.
- IMPORTFEED: RSS and Atom feeds.
- IMPORTRANGE: Ranges from other spreadsheets.
- REGEX functions: Clean up what was imported.
- QUERY: Filter and group imported rows.
Scraped cells are fine for a watchlist, fragile for a report
Scraped cells are fine for a watchlist, fragile for a report
IMPORTXML is a good way to keep an eye on a few public pages. It is a poor foundation for reporting: the result depends on the layout of a page someone else controls, refreshes on its own schedule, and returns an error or nothing when the page changes. Business numbers such as spend, orders and revenue have better sources than the HTML of a page.
The OWOX Data Marts extension for Google Sheets covers that half. A data analyst publishes a data mart (a table or an SQL query in your data warehouse) and makes it available for reports. In Sheets you open the extension, pick the data mart, tick the columns you want and run it. The rows land in a tab, ready for your formulas.
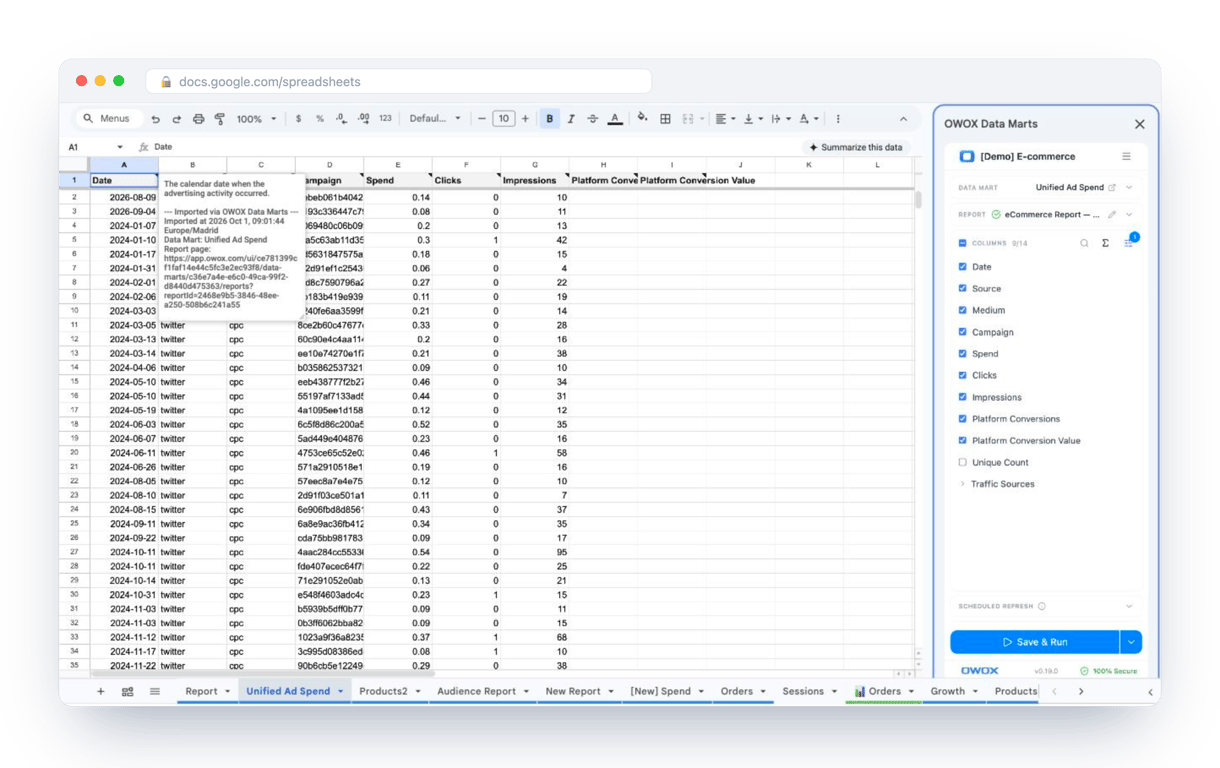
What changes for the person who maintains the sheet:
- Refresh replaces re-export. Refresh current report in the extension menu re-runs the same pull, and a scheduled refresh keeps the tab current without anyone touching it.
- The source is written on the sheet. The header cell of an imported tab carries a note with the data mart it came from, the time of the import and a link to the report.
- No SQL and no warehouse access needed. The analyst decides which data marts and columns are available. You choose from that list.
The extension does not write or change the analyst’s SQL. The numbers in the report then come from the warehouse on a schedule you set, and IMPORTXML stays what it is good at: a quick look at public pages. The extension comes with the OWOX Cloud plans of OWOX Data Marts; spreadsheet reporting describes both ways data reaches a sheet.
Turn your data into decisions.
Governed data marts give you the clean foundation ML needs to actually work.
- No AI hallucinations
- Analyst-governed definitions
- Every number traces to SQL
Frequently Asked Questions
How do I refresh ImportXML data automatically in Google Sheets?
IMPORTXML re-reads the page by itself: Google's help says it checks for updates every hour while the spreadsheet is open. Reloading the page does not trigger a refresh. To request the page again sooner, delete the formula and enter it again.
Why is ImportXML returning a blank result in Google Sheets?
This usually happens when the XPath doesn’t match any element on the page or the data is loaded via JavaScript. Double-check your XPath, ensure the content exists in the static HTML, and verify that the site is accessible.
What is the alternative to ImportXML?
For a table or a list on a page, IMPORTHTML is simpler and needs no XPath. IMPORTDATA reads CSV and TSV files, IMPORTFEED reads RSS and Atom feeds, and IMPORTRANGE reads other Google spreadsheets. For pages that build their content with JavaScript or need a login, a spreadsheet function is not enough: use the site's API or export.
What is the limit of ImportXML in Google Sheets?
IMPORTXML reads only public pages and only the HTML the server sends: content behind a login or added by JavaScript is not available. Sites can refuse automated requests, the data refreshes about once an hour, and many import formulas in one file make it slow. For large volumes of pages a dedicated crawler is the better tool.
What is ImportXML in Google Sheets?
ImportXML is a function in Google Sheets used to import data from XML, HTML, and XHTML sources. It uses Xpath queries to pinpoint and extract specific information, ideal for detailed data analysis from web pages.