BigQuery wildcard tables and _TABLE_SUFFIX, with measured costs
A wildcard table queries every table whose name starts with a prefix, such as the daily tables of the GA4 export, and the _TABLE_SUFFIX pseudocolumn says which ones to read. This guide measures the bytes a query reads with and without the filter on Google's public GA4 sample, shows the filter form that silently reads everything, and covers schema, limits and when a partitioned table is the better choice.
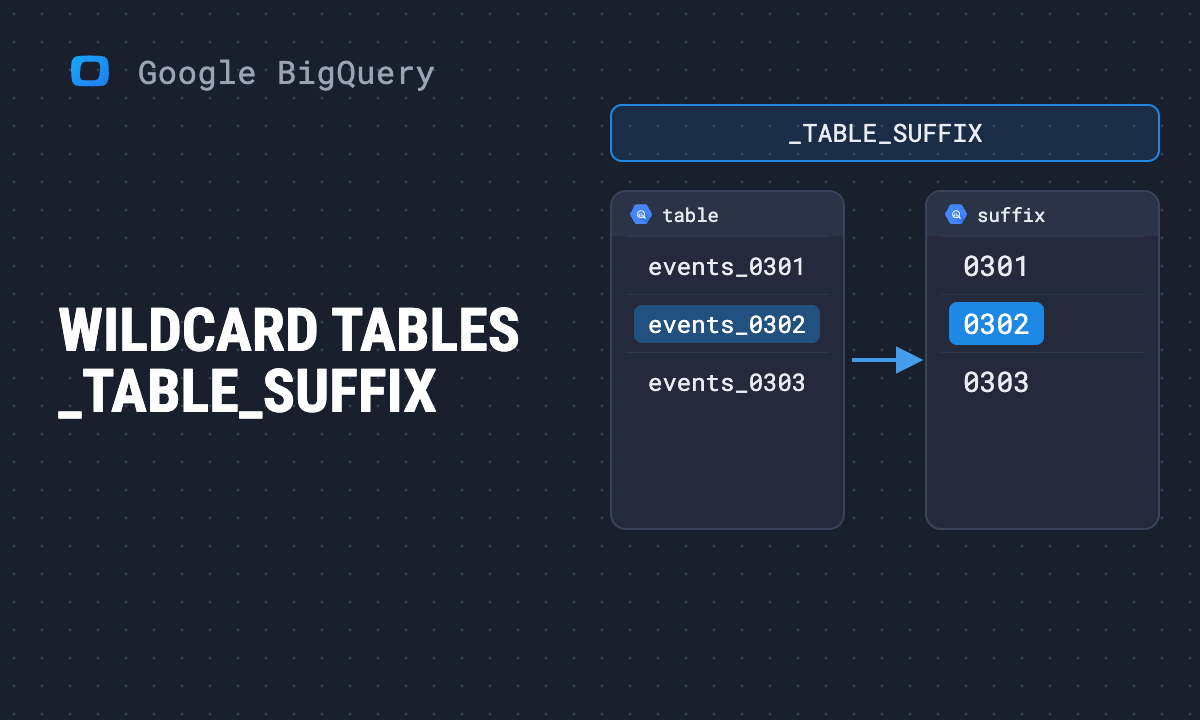
A wildcard table is a query over every table whose name starts with a prefix. FROM project.dataset.events_* reads events_20210101, events_20210102 and every other table that matches, as if they were one. The pseudocolumn _TABLE_SUFFIX holds the part of the name the * replaced, and a filter on it decides which tables are read and billed.
SELECT event_name, COUNT(*) AS events
FROM `bigquery-public-data.ga4_obfuscated_sample_ecommerce.events_*`
WHERE _TABLE_SUFFIX BETWEEN '20210101' AND '20210107'
GROUP BY event_name;
The GA4 export is the main reason most people meet wildcards: it writes one table per day, events_YYYYMMDD. The public sample used here has 92 of them, from events_20201101 to events_20210131.
Note: Originally published in July 2024. Fully rewritten in October 2026: every result and byte count below was produced in BigQuery on 16 October 2026; byte counts come from dry runs, which report what a query would read without running it.
The filter is the cost
The same column, read three ways:
Query on events_* |
Bytes read |
|---|---|
no filter on _TABLE_SUFFIX |
55.95 MB |
WHERE _TABLE_SUFFIX BETWEEN '20210101' AND '20210107' |
3.17 MB |
WHERE _TABLE_SUFFIX IN (SELECT '20210101') |
55.95 MB |
The constant filter reads 7 days out of 92. The third query asks for one day and is billed for all 92: BigQuery could not work out from that subquery, before running it, which tables it needs. Filters built from constants and functions of constants do prune: BETWEEN FORMAT_DATE('%Y%m%d', DATE '2021-01-01') AND FORMAT_DATE('%Y%m%d', DATE '2021-01-07') also read 3.17 MB, and _TABLE_SUFFIX IN UNNEST(['20210101', '20210102']) read 0.59 MB. Some subqueries over constants prune too; a filter that reads another table, such as a list of dates kept in a table, does not. The rule that never fails: check the estimate before you run.
On a real GA4 property, where a day can be gigabytes, that difference is the bill. For a rolling window use a date function, not a lookup:
WHERE _TABLE_SUFFIX BETWEEN
  FORMAT_DATE('%Y%m%d', DATE_SUB(CURRENT_DATE(), INTERVAL 7 DAY))
  AND FORMAT_DATE('%Y%m%d', DATE_SUB(CURRENT_DATE(), INTERVAL 1 DAY))
LIMIT does not reduce the cost
SELECT * FROM events_2021* LIMIT 1 was estimated at 957 MB. LIMIT cuts the rows returned, not the data read; BigQuery still scans every column of every matching table. Preview a table in the console’s Preview tab instead, which is free.
_TABLE_SUFFIX as a column
_TABLE_SUFFIX can be selected and grouped like any column:
SELECT _TABLE_SUFFIX AS day, COUNT(*) AS events
FROM `bigquery-public-data.ga4_obfuscated_sample_ecommerce.events_*`
WHERE _TABLE_SUFFIX BETWEEN '20210101' AND '20210103'
GROUP BY day
ORDER BY day;| day | events |
|---|---|
| 20210101 | 22096 |
| 20210102 | 23599 |
| 20210103 | 24743 |
It is a STRING. Compare it with strings in the same format, '20210101', not with a DATE. PARSE_DATE('%Y%m%d', _TABLE_SUFFIX) turns it into a date for display.
OWOX Data Marts
See your first report built in real time. 15 minutes.
- Connect your data warehouse
- Pick your metrics
- Get a live Google Sheets report
In the time it takes to write a ticket. Then imagine never writing that ticket again.
Book a DemoWe'll use your actual use case
Choosing the prefix
The wildcard matches everything after the prefix, which can include tables you did not mean:
events_*in a GA4 dataset also matchesevents_intraday_20260915, the streaming tables. Their suffix starts withintraday_, so aBETWEEN '2026…'filter leaves them out, but an unfiltered query or aLIKEfilter can include them and double-count today.- A longer prefix narrows the match:
events_2021*reads only tables from 2021, and its_TABLE_SUFFIXis then0101,0102and so on.
To list what a wildcard will match, query the dataset’s INFORMATION_SCHEMA.TABLES with table_name LIKE 'events_%'.
Schema and limits
- The schema is taken from the most recently created matching table. If an old table lacks a column, its rows return NULL for it; if the newest table drops one, the query cannot select it.
- Wildcards work on standard tables only, not on views or external tables.
- Results are not cached; the same query runs and bills again.
- For loading data into one of the tables, write to the specific table name, not to the wildcard.
Wildcard tables or a partitioned table
Wildcard tables or a partitioned table
Date-named tables are an older pattern. Google recommends partitioned tables instead, and for data you control they are better: one table, one schema, the same pruning with an ordinary WHERE on a date column, and require_partition_filter to reject queries that forget it. The comparison and the measured pruning are in partitioned tables.
You will still use wildcards for data written by someone else, the GA4 export first of all. A common step is a scheduled query that reads yesterday’s events_ table and appends it to a partitioned table your reports use. The first queries to run on the export are in BigQuery query examples, and the export itself in the GA4 to BigQuery guide.
Combining tables without a wildcard
Combining tables without a wildcard
When the tables do not share a prefix, write them out with UNION ALL. Each part must return the same columns in the same order and types. The difference between UNION ALL and UNION DISTINCT, and why the second can drop real rows, is in JOIN and UNION.
One query, read by everyone
A wildcard query with the right suffix filter is easy to get wrong in a copy: someone replaces the date function with a lookup and the cost multiplies, or widens the prefix and counts today twice. Write it once, check its bytes, and let reports read the result. In OWOX Data Marts that query is a Data Mart that runs on a schedule in your own BigQuery project and feeds sheets and ; OWOX Data Marts does not transform the data. More on what queries cost in BigQuery pricing.
Turn your data into decisions.
Governed data marts give you the clean foundation ML needs to actually work.
- No AI hallucinations
- Analyst-governed definitions
- Every number traces to SQL
Frequently Asked Questions
How does _TABLE_SUFFIX work in BigQuery?
In a query on a wildcard table such as events_*, _TABLE_SUFFIX holds the part of each table's name that the * replaced, for example 20210101. A filter on it with constant values decides which tables are read: on Google's GA4 sample, 7 days read 3.17 MB against 55.95 MB for all 92.
Why does my _TABLE_SUFFIX filter not reduce the bytes processed?
BigQuery prunes tables only when it can tell before running which ones the filter needs. Constants and functions of constants work. In our test, _TABLE_SUFFIX IN (SELECT ...) read every table, and so does a filter that reads another table. LIMIT never reduces the bytes. Check the estimate before running.
How do I query a range of dates in the GA4 export with a wildcard?
FROM project.analytics_XXX.events_* WHERE _TABLE_SUFFIX BETWEEN '20260901' AND '20260930'. For a rolling window, use FORMAT_DATE('%Y%m%d', DATE_SUB(CURRENT_DATE(), INTERVAL 7 DAY)) as the lower bound.
When should I use wildcard tables in BigQuery?
For data that arrives as one table per day, written by someone else, such as the GA4 export. For data you control, a partitioned table does the same pruning with an ordinary WHERE on a date column and has one schema.
What are the limits of BigQuery wildcard tables?
They work on standard tables only, not views or external tables; query results are not cached; and the schema is taken from the most recently created matching table, so older tables missing a column return NULL for it. A short prefix can also match tables you did not mean, such as events_intraday_.
What is the difference between wildcard tables and partitioned tables?
A wildcard queries many separate tables that share a name prefix; a partitioned table is one table split by a column. Both prune by date, but a partitioned table has one schema, can require a partition filter and is what Google recommends for new data.